Stop Treating Images as Text: Elorian’s Glimpse Changes the Game
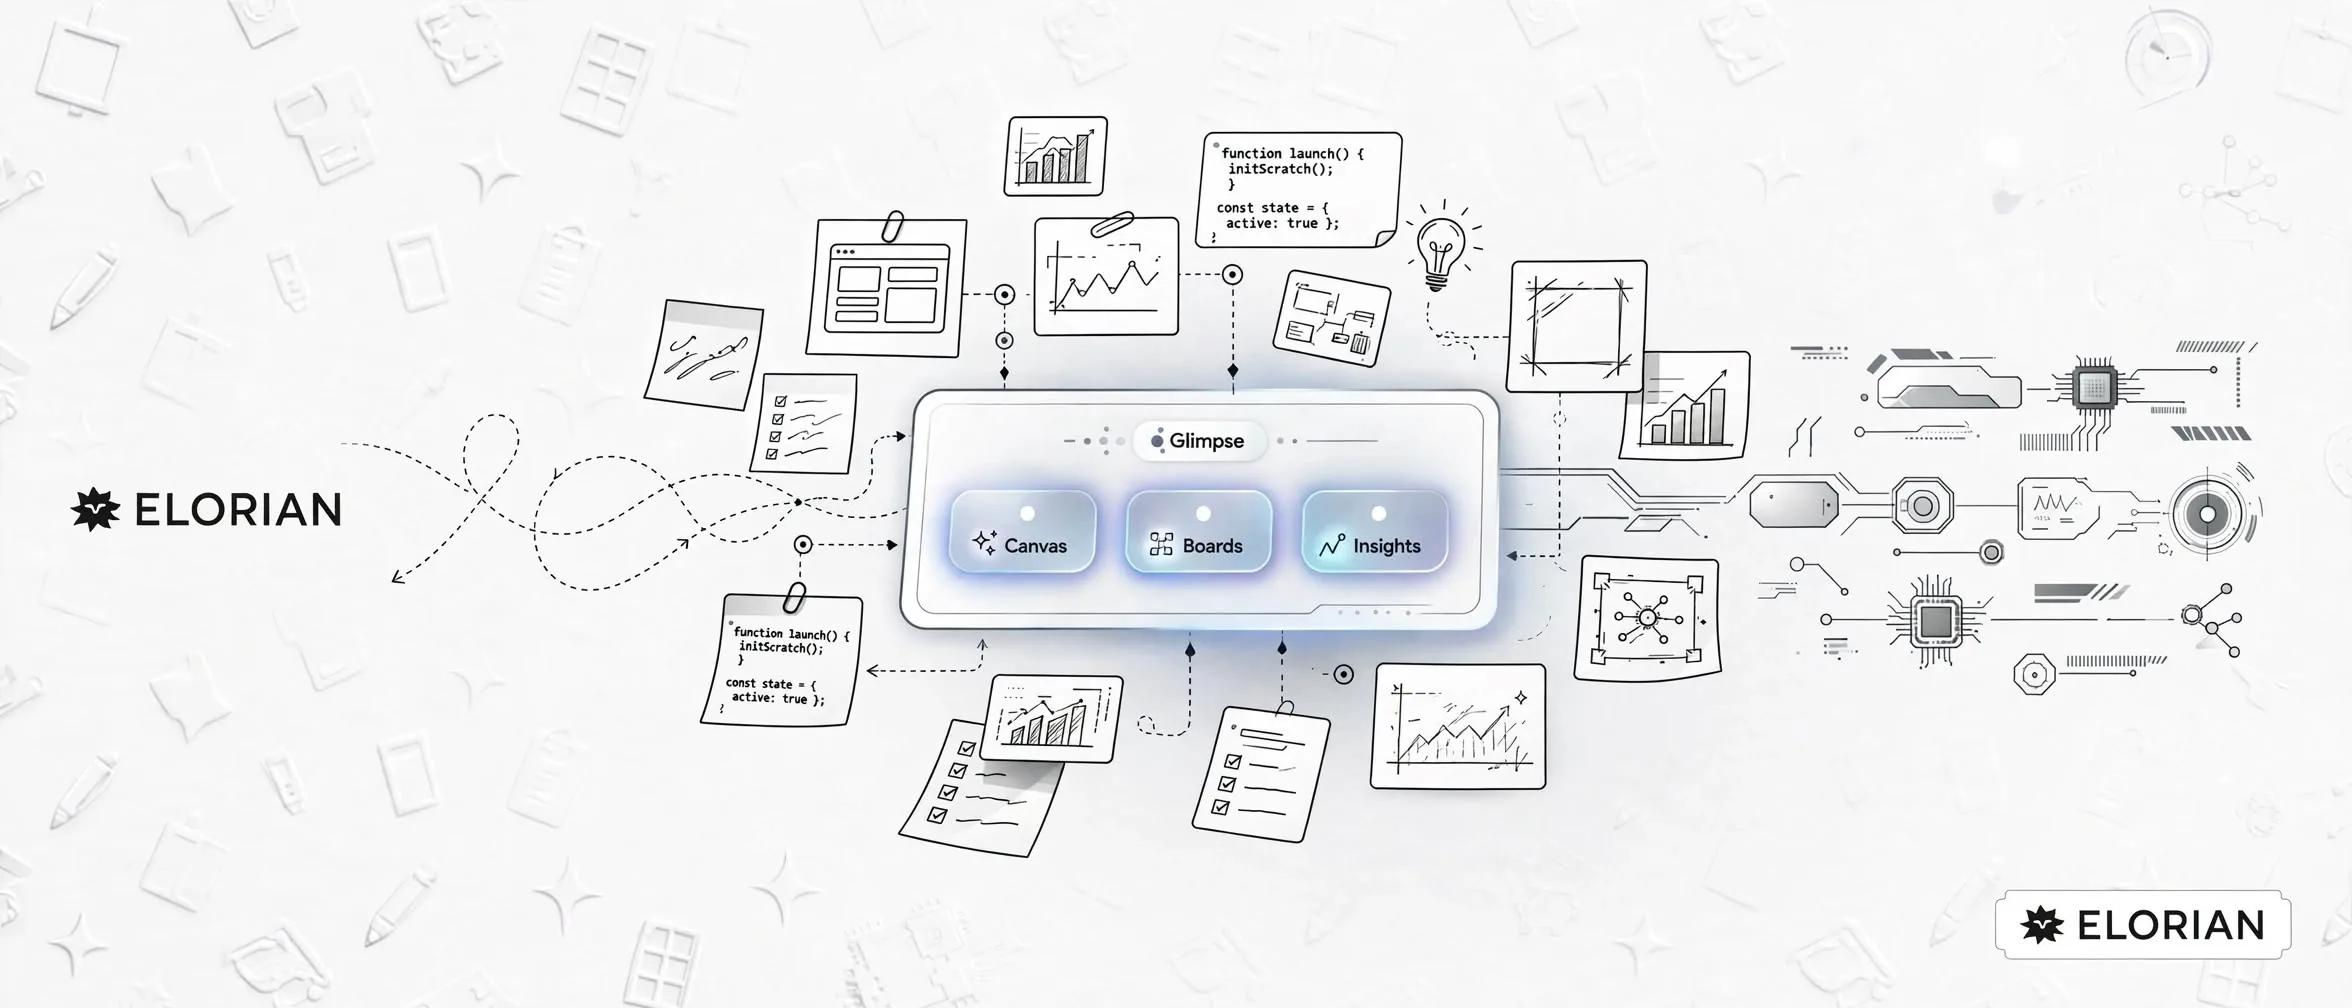
How Glimpse actually 'sees'
According to TechCrunch, Elorian is moving away from the industry standard of converting images into static text tokens. Most models look at an image once and then 'hallucinate' or reason based on that initial memory. Glimpse, however, uses a visual scratch space.
This allows the model to perform a digital version of 'pinching to zoom.' During the reasoning process, it can crop into specific areas, extract frames from a video, or execute code to measure elements it is currently analyzing. This iterative process is designed to solve the common issue where AI fails to interpret complex iconography or symbols in specialized diagrams.
How it performs in the real world
Elorian claims Glimpse outperforms GPT-6 Astra in scientific chart reasoning and short-form video captioning. The efficiency gains are notable: the model was trained by a small team using only a few hundred GPUs, making it significantly smaller than the massive frontier models it competes against.
For the user, this means a different cost structure. Glimpse is priced at $0.60 per million input tokens and $3 per million output tokens. While it is more expensive than lightweight models like Haiku or Luna, it targets high-stakes industries like robotics, scientific research, and media production where precision in visual interpretation is non-negotiable.
Verdict: Is it worth the switch?
If your workflow involves analyzing technical schematics, board game logic, or dense video content, Glimpse is worth monitoring. The ability to 're-look' at data mid-process reduces the risk of misinterpretation that plagues current multimodal systems.
However, it is currently in a research preview phase with waitlist-only access to the chat interface. If you are building automated pipelines for robotics or creative media, the API access is the primary entry point to test whether this 'scratch space' architecture provides the accuracy boost your specific use case requires.
Sources
Frequently asked questions
- How does Glimpse differ from other multimodal models?
- Unlike models that convert images to text tokens once, Glimpse can re-examine image regions or video frames during the reasoning process using a 'visual scratch space'.
- What is the cost of using Glimpse?
- Glimpse is priced at $0.60 per million input tokens and $3 per million output tokens, positioning it between lightweight models and high-end frontier systems.
Comments
0 commentsDeixe seu comentário
Be the first to comment.
Continue Lendo
When AI Censorship Fails: Meta’s Brazilian Election Crisis
Meta AI sparks political crisis in Brazil
Why the G7 Is Suddenly Simulating AI Cyberattacks on Banks
G7 prepares emergency drills for AI cyberattacks
Google AI Overviews Are Changing: More Traffic for Sites?
Google gives more prominence to AI links